On Monday, a business owner emails three vendors: “We need an AI chatbot for our website.” By Friday, three proposals arrive—for €3,000, €18,000, and €70,000. One is a polished FAQ widget. Another includes CRM integration. The third is an autonomous agent that can change orders. The quotes cannot be compared because each vendor priced a different product.
This guide gives you a copy-ready AI assistant project brief that you can send to an internal team, freelancer, or development agency. You do not need to understand vector databases or agent orchestration. You need to understand your operation: who needs help, what they are trying to do, where the correct answer lives, and who is allowed to press the final button.
This is not a contract or a complete technical specification. It is a business brief precise enough to filter out incompatible proposals, expose hidden costs, and start a serious pilot conversation.
Choose which of three products you actually need
“Chatbot” is used for at least three different systems. The distinction changes cost, delivery time, and risk far more than the model name does.
| Level | What it does | Example | Main difficulty |
|---|---|---|---|
| 1. Adviser | Finds approved information and answers | Explains a delivery policy or plan | Knowledge quality and freshness |
| 2. Copilot | Reads operational data and prepares work for a person | Looks up an order and drafts the reply | Integrations, identity checks, staff workflow |
| 3. Agent | Takes action in other systems | Creates a case, books a slot, or changes a record | Permissions, errors, approval, and rollback |
For many small businesses, a copilot is the sensible first release. It removes searching and rewriting while a person still sees the decision before it affects money, a customer, or the system of record. Add autonomy one narrow action at a time after the workflow proves itself on live traffic.
The one-page AI assistant brief
Fill the gaps in ordinary language. If you do not know something yet, write “to be established during discovery.” That is more useful than an invented requirement.
PROJECT NAME
[Short working title]

BUSINESS PROBLEM
Today, [who] spends [time/money] on [process], causing [consequence].

PILOT OUTCOME
Within [period], move [metric] from [baseline] to [target]
without worsening [guardrail metric].

USERS AND CHANNEL
Users: [customers / staff / partners]
First channel: [website / email / messaging / CRM]
Languages: [list]
Expected volume: [conversations or tasks per week]

VERSION-ONE SCENARIOS
1. [Request → required result]
2. [Request → required result]
3. [Request → required result]

OUT OF SCOPE
[Scenarios, channels, and actions deliberately excluded]

SOURCES OF TRUTH
[System/document] — [owner] — [update frequency]

INTEGRATIONS
Read: [fields from named systems]
Write: [narrow actions, if any]
Human approval required for: [list]

MANDATORY ESCALATION
[Money, personal data, conflict, uncertainty, exceptions]
Queue owner: [role]
Response target: [SLA]

ACCEPTANCE CRITERIA
[Real test set, required quality, zero-tolerance failures]

OPERATIONS
[Logs, analytics, retention, monitoring, kill switch]

PROPOSAL FORMAT
Price discovery, pilot, integrations, evaluation, production launch,
third-party monthly costs, and support separately.
The 30-second test. A stranger should understand what work the assistant takes on, where it gets the truth, what it cannot do, how it hands work to a person, and how you will decide whether it passes.
Describe an outcome, not AI magic
“Improve service with AI” cannot be evaluated. “Reduce median drafting time for order-status replies from six minutes to two without increasing repeat contacts” can.
A good objective has an operating metric and a guardrail. One captures the benefit; the other stops the team from achieving it in a damaging way.
| Weak objective | Operating metric | Guardrail |
|---|---|---|
| Reply faster | Median time to first useful answer | Repeat-contact rate does not rise |
| Qualify more leads | Leads with complete context in CRM | Qualified-to-meeting conversion does not fall |
| Reduce workload | Manual minutes per case | Critical escalations are never missed |
| Automate documents | Time from receipt to usable draft | Zero unverified amounts or account details |
Measure the baseline before the project starts. Otherwise, you may have an impressive demo without knowing whether the business improved. Use our automation ROI guide when the financial case matters.
Build scenarios from real work
Do not invent a “typical customer” in a workshop. Take 50–100 real messages or tasks, remove unnecessary personal data, and group them by the next action. Real examples reveal spelling mistakes, mixed languages, voice transcripts, several intents in one message, and questions your own team does not answer consistently.
Give every scenario a row:
| Input | Required result | Data | Allowed action | Stop condition |
|---|---|---|---|---|
| “Where is my order?” | Verified status and tracking | Order number + second customer signal | Read only | Details do not match |
| “Will this fit model X?” | Confirmed compatibility | Current product catalogue | Answer with source | No explicit confirmation exists |
| “I want a demo” | Qualified lead | CRM, calendar, ICP criteria | Offer an allowed slot | Non-standard contract or consent issue |
Limit the first release to three to five frequent scenarios. Everything else is explicitly out of scope or routed to a person. “Answer any question about the company” is not a requirement. It is an incident backlog.
Name the sources of truth
AI does not fix contradictory data. It merely finds one version faster. Every fact category needs a named source, an owner, and a freshness rule.
Delivery terms: public policy page
Owner: operations manager
Update: after a carrier or rate change
Priority: above old PDFs and chat messages

Price and stock: catalogue/ERP API
Owner: ecommerce manager
Update: real time
Rule: never take prices from historical conversations
Do not ask a vendor to “ingest the whole Drive.” Prepare a small register: source name, data type, owner, last review, permitted users, retention period, and priority when sources conflict.
If the data includes personal, payment, health, or other sensitive information, specify which fields may be transferred, who may see them, where they are processed, and when they are deleted. “Must be GDPR compliant” is not enough; ask for the actual data-flow description.
Separate answers, actions, and approvals
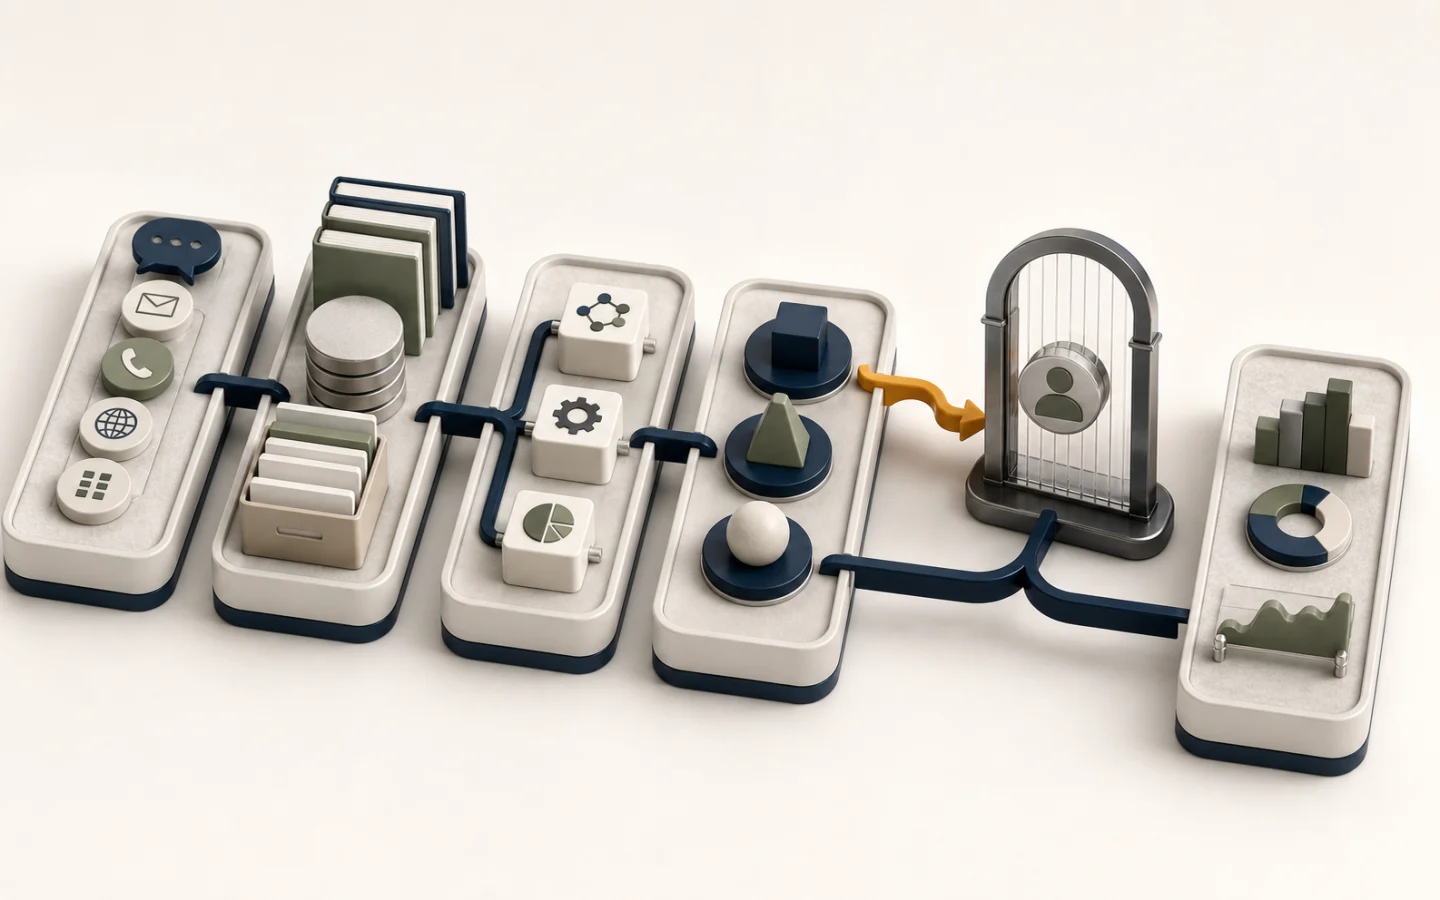
Do not write “connect the CRM” in the integration list. Name the objects, fields, and permissions. Reading a contact, creating a note, changing a deal stage, and deleting a deal are four different rights.
| Level | Example | First-release rule |
|---|---|---|
| Answer | Explain an approved policy with a link | May automate after tests |
| Draft action | Prepare a CRM note or email | A person reviews and confirms |
| Reversible action | Add a tag or create a task | Narrow permission, audit log, undo path |
| High-risk action | Refund money, alter a booking, send a contract | Explicit human approval |
| Irreversible action | Delete data or settle a financial operation | Out of scope for version one |
OWASP treats prompt injection and excessive agency as major risks in LLM applications and recommends least-privilege access, tool-call validation, and human approval for privileged operations. Customer text, email, web pages, and documents are untrusted input even when they look like ordinary instructions.
Put one hard rule in the brief: authorization, value limits, and permission to act must be enforced by deterministic application code—not by the language model. A model may propose a refund; your rules engine decides whether the approval button may appear at all.
Write acceptance tests before development
“Works well” is not an acceptance criterion. Before development, assemble a private test set of real examples that the implementation team does not tune against. Include ordinary, ambiguous, rare, and intentionally hostile cases.
- a common question with one clear answer;
- typos, shorthand, and conversational language;
- each launch language and a mid-conversation language switch;
- multiple intents in one message;
- a missing required field;
- conflicting sources;
- a question the sources cannot answer;
- an invalid identifier or failed identity check;
- a request for a prohibited action;
- an “ignore previous rules” instruction inside a message or document;
- an unavailable CRM, slow API, or model timeout;
- a repeated action that could create a duplicate.
For each test, state expected facts, allowed and forbidden actions, and the escalation route. Score routing, factual grounding, data exposure, unwanted action, audit completeness, and latency separately. One average “accuracy” number hides the failures that matter.
- Zero tolerance: another customer’s data, invented financial promises, or unintended actions.
- Quality threshold: set on your own examples for each scenario and language.
- Fallback: uncertainty, integration failure, or invalid output routes to a person.
- Shadow launch: the system handles early live cases without sending or writing.
NIST frames AI risk management as a lifecycle discipline: govern, map, measure, and manage. In a practical brief, that means a quality owner, a recurring review sample, an incident register, and the ability to return the system to draft-only mode quickly.
Specify how the system will operate
A demo shows the best minute of a system. The brief must describe the rest of the year:
- latency: acceptable response time and timeout behaviour;
- availability: operating hours, fallback route, and outage message;
- audit: input, sources, rule version, tool calls, approvals, and final outcome;
- privacy: masking, retention, deletion, roles, and export;
- cost controls: request limits, anomaly alerts, and cost at 2× and 10× volume;
- change management: who updates knowledge and how new versions are tested and rolled back;
- support: who responds to incidents and third-party API changes;
- exit: how data, configuration, tests, and logs are exported when you change vendors.
If your business does not yet have owners for sources, access, and baseline metrics, start with our guide to making an online business AI-ready. It often removes the most expensive ambiguity before development.
Get comparable estimates
Do not request one all-in figure. Ask every vendor to price the same work packages and state their assumptions.
| Work package | What the estimate should include | What is often missed |
|---|---|---|
| Discovery | Process, data, risks, workflow prototype | Your staff time |
| Pilot | One channel, 3–5 scenarios, drafts, analytics | Preparing real test cases |
| Integrations | Each system, object, direction, and permission | API limits and paid connectors |
| Security | Roles, secrets, filters, approvals, audit | Pen testing and remediation |
| Production | Monitoring, alerts, rollback, documentation | Moving beyond the demo environment |
| Monthly | Models, hosting, channels, support | Human review and retries |
Request operating estimates at current, double, and ten times the volume. Separate fixed build cost, forecast third-party charges, and on-demand support. A cheap prototype can be an expensive service if scaling and human review are omitted.
Compare more than totals. Look for the vendor that tests assumptions, narrows permissions, proposes shadow mode, clarifies ownership, and explains what happens when a model, price, or API changes.
Two completed examples
Ecommerce support copilot
Problem: two agents manually search orders and policy documents;
messages are missed between email and web chat at peak times.

Pilot outcome: reduce median ORDER_STATUS drafting time
from 5 minutes to 2; repeat-contact rate does not increase.

First release: email, Ukrainian and Russian, 600 contacts/week.
Scenarios: status, delivery, return information collection only.

Sources: order system, carrier API, active policy cards.
Actions: read status and draft. Never alter an order.

Escalate: failed verification, money, address change, conflict,
or missing fact. Owner: duty manager. SLA: 30 minutes.

Acceptance: 120 held-out cases; 100% risky actions escalated;
zero data leaks; zero invented status or delivery promises.
For the full implementation sequence, read our seven-day ecommerce AI support playbook.
B2B lead qualification assistant
Problem: the founder takes 12–15 calls each week;
one-third do not meet the minimum customer profile.

Pilot outcome: 80% of enquiries have complete context before a call;
qualified-to-meeting conversion does not decline.

First release: website form + email, English and Ukrainian.
Scenarios: collect problem, deadline, source system, role, and volume.

Sources: ICP criteria, service catalogue, calendar, CRM.
Actions: draft a lead record and offer approved slots.
Never invent the buyer's budget or promise a delivery date.

Escalate: tender, regulated data, custom contract, unclear fit.
Owner: business development.

Acceptance: 80 historical leads + 30 edge cases;
no potentially valuable lead is rejected automatically.
15 questions to ask a vendor
- Which assumption in our brief has the largest cost impact?
- What have you deliberately excluded from version one?
- How does the system show the source for each fact?
- What happens when sources conflict?
- What exact permissions does each integration receive?
- Which checks are enforced in code outside the model?
- Where is human approval required, and what does it look like?
- How do you test prompt injection and unintended actions?
- Who owns the evaluation set after the project?
- What happens when the CRM is unavailable or the model times out?
- What is logged, who can see it, and when is it deleted?
- What does operation cost at 1×, 2×, and 10× volume?
- Who updates knowledge and owns regression testing?
- How can automatic actions be disabled without taking the service down?
- What can we export if we change vendors?
Proposal red flags
- a precise “95% accuracy” promise before reviewing your cases;
- one price without assumptions, integration detail, or monthly costs;
- “train on all your data” without a source register and access rules;
- administrator permissions for convenience;
- security described only through a system prompt;
- a demo with no shadow test, audit trail, or emergency control;
- unclear ownership of code, configuration, prompts, and tests;
- exceptions postponed until later while the initial launch is autonomous.
A capable vendor will not promise that the model never fails. They will show how the system detects uncertainty, limits consequences, gives a reviewer useful context, and turns every important failure into a regression test.
Frequently asked questions
Do we need a full technical specification before speaking to developers?
No. A one-page business brief is enough for initial discovery and a directional estimate. The detailed specification follows process, data, and integration validation.
How many scenarios belong in an AI assistant MVP?
Three to five frequent, well-defined scenarios usually make a better pilot than broad coverage. Add each new scenario only after giving it its own tests.
Should the first version connect to our CRM?
Only when current CRM data is necessary for a useful outcome. Begin with read-only access to the minimum fields, then add narrow write actions separately.
How should we evaluate AI chatbot quality?
Use a held-out set of real cases and score factual grounding, routing, escalation, data exposure, unintended actions, languages, failures, and latency separately.
What matters more when choosing a vendor: portfolio or price?
Look for the ability to understand the operation, constrain permissions, define verifiable acceptance tests, and hand over a service your team can run. Portfolio and price matter, but predict little without those capabilities.
Sources and further reading
- OWASP: Prompt Injection — untrusted instructions, least privilege, and approval controls.
- OWASP: Excessive Agency — excessive functions, permissions, and autonomy.
- NIST AI Risk Management Framework — lifecycle governance, measurement, and risk management.
The best brief does not try to make every technical decision in advance. It does something more important: it leaves little room for conflicting interpretations of the outcome. That is where an honest estimate, a safe pilot, and a system that works beyond the demo begin.